The Tell
A blind judging game: pick the work you prefer, guess which was hand-made, and see how well you can really tell.
Read more FirasaRead the signs. Test the reading.
Firasa helps organisations put AI to work, measure what matters, and find out honestly whether it worked.
Psychology-trained. AI-native. Sydney.
01 / Sixty seconds
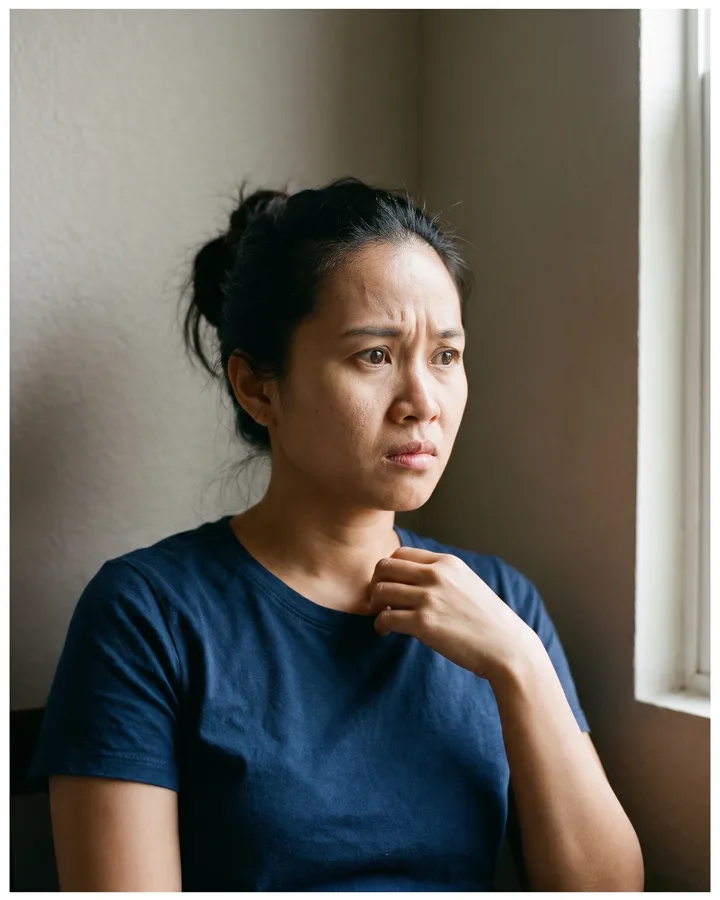
Two portraits, five personality traits each. Rate what you see, or say when you cannot tell. Then find out which answers you could have defended. It takes a minute, and it is the quickest way to see what I do for a living: check a confident reading before anyone acts on it.
02 / Which sounds like your week?
03 / How I work
04 / Projects you can open
Every project, with its real status ↗Two you can try in a browser, one you can run, one you can explore and one still being built. Each page says what has and has not been tested.
A blind judging game: pick the work you prefer, guess which was hand-made, and see how well you can really tell.
Read moreAn interview that turns what someone says into evidence-backed readings, with their own words kept attached.
Read moreA team of AI agents that designs a custom benchmark for an AI system, checked the way a psychological test is checked.
Read moreAn open playground of psychology-based patterns for controlling AI agent loops, and for measuring whether they help.
Read moreCountry governance profiles on five dimensions, compared within regime type, with uncertainty shown and no league table.
Read more05 / AI evaluations
A benchmark, an AI judge and an interpretability probe all claim to measure something about a model. Psychology has spent a century learning how to check claims like that. I bring those checks to AI evaluation.
06 / Latest perspective
All perspectives ↗Hiring, promotion and reward as firāsa practised with imperfect tools
Read the essay ↗A small measurement experiment
Add evidence to a plausible first impression. The point is not to reveal the answer. It is to see what the answer can survive.
Two plausible readings
The passing suite and smaller surface suggest a well-scoped change.
The suite may simply be unable to see the failure that matters.
No additional evidence selected. Both readings remain plausible.
Synthetic example. No codebase was assessed, and no reliability or validity claim is being made.
The website is an instrument, too.
A few seconds on a page. A click on a paper. Enough to build a story about you?
Try a small experiment in how observation becomes inference, and how easily inference becomes marketing.
Opt in to count section visibility, selected clicks and scroll depth. The readings stay in this page’s memory and disappear on reload. No cookies or analytics uploads are used by this experiment.